Many technology leaders eventually inherit the same uncomfortable question: is it cheaper to keep patching this system, or to finally replace it? The honest answer is usually buried under years of undocumented decisions, departed engineers, and quarterly priorities that never left room for a proper look under the hood. A software systems audit is how that answer gets found - through a structured, evidence-based review of what it does now, what it costs, and what it risks.
This article lays out a practical framework CTOs and CIOs can use to decide, system by system, whether to fix, replace, or retire - along with what a proper audit actually involves, how long it takes, and what pitfalls tend to derail the decision. Whether you're running the audit yourself, commissioning one, or simply trying to bring more rigor to a software modernization conversation, the goal is the same: turn a subjective call into a defensible one.
Why technical debt decisions fail without a structured framework
Most fix-replace-retire decisions aren't actually decisions - they're defaults. A system keeps getting patched because rewriting it feels too risky, or it keeps getting funded because no one wants to be the one who "broke" a revenue-generating platform. Neither outcome is wrong by definition, but neither is chosen deliberately either. That's the core problem with informal technical debt assessment: it optimizes for whoever argued most recently, not for what the evidence actually shows.
The absence of a framework tends to produce two failure modes. The first is chronic underinvestment, where systems accumulate risk quietly until an outage or security incident forces an emergency response under the worst possible conditions. The second is the opposite - a sweeping, high-drama rewrite triggered by frustration rather than data, which burns budget replacing components that were never actually the problem. A working framework exists precisely to sit between these extremes, forcing the same criteria to be applied to every system under review so that the loudest complaint in the room doesn't automatically win. With that in mind, it helps to define exactly what those criteria should be.
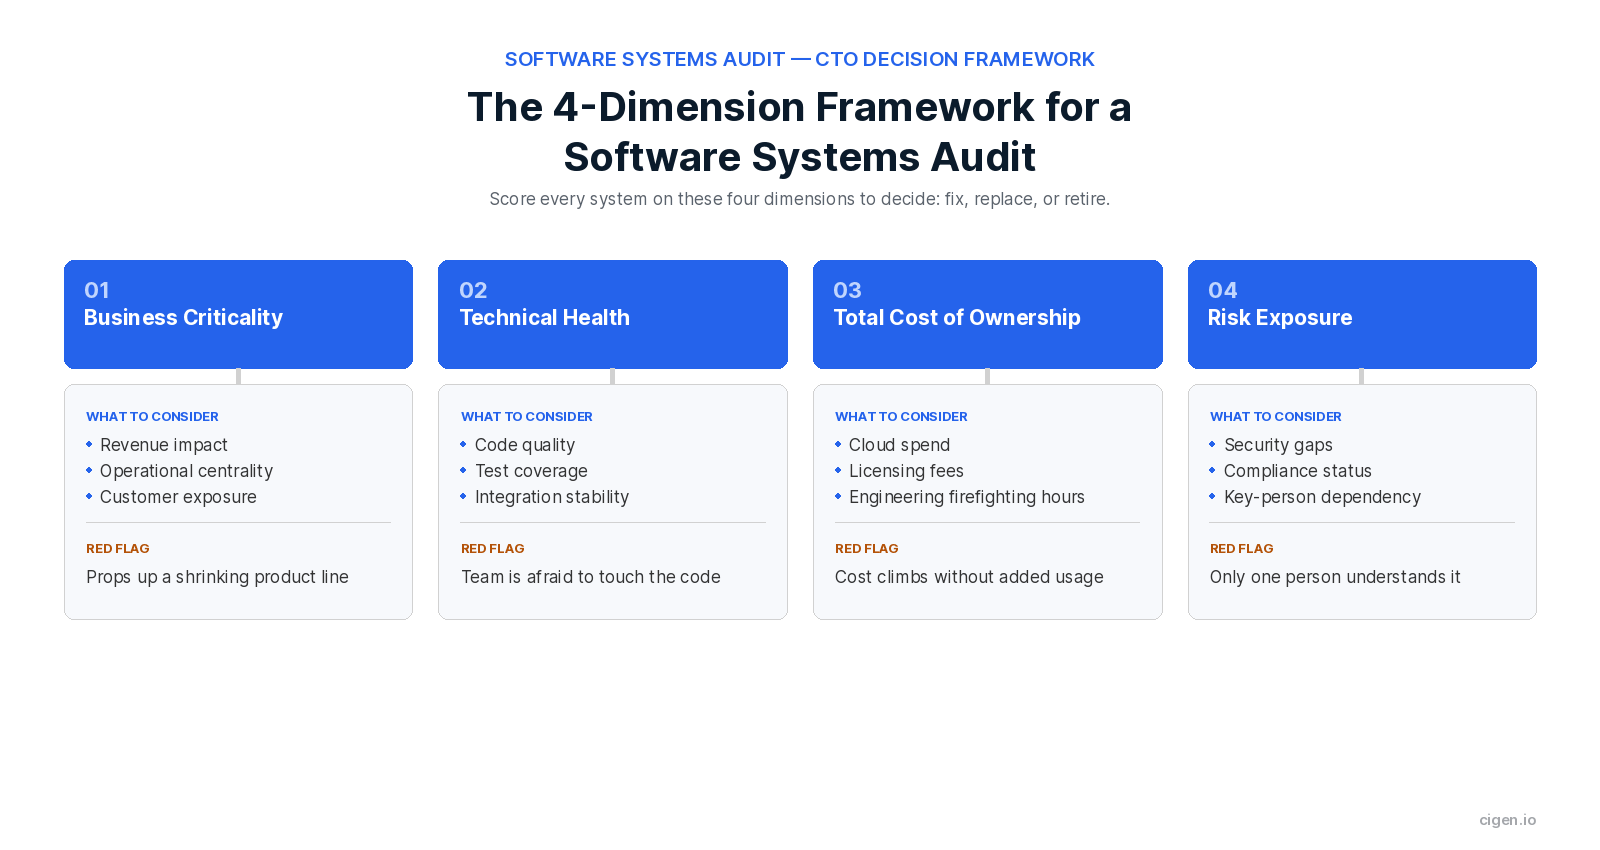
The 4-dimension technical audit framework: business criticality, technical health, cost, and risk
A defensible fix-replace-retire decision rests on scoring each system against four dimensions, independent of how the system was originally built or who built it. Taken together, these dimensions turn a vague sense of "this system feels old" into a structured application rationalization exercise that can be repeated consistently across a portfolio.
- Business criticality asks how central the system is to revenue, operations, or customer experience today - not how important it was five years ago. A system that quietly supports a shrinking product line scores very differently than one processing every customer transaction, even if the two look similarly outdated from the outside.
- Technical health captures the state of the codebase, architecture, and test coverage: how much technical debt has accumulated, how brittle the integrations are, and how confidently a team can make changes without breaking something else. This is usually where legacy system evaluation gets the most attention, because it's the dimension most visible to engineering teams day to day.
- Total cost of ownership goes beyond the visible infrastructure bill to include the hidden costs of maintaining the system: cloud spend, licensing, the engineering hours consumed by firefighting, and the opportunity cost of specialists who could otherwise be building new capability.
- Risk exposure rounds out the picture - security vulnerabilities, compliance gaps, and a particularly common but underrated risk: key-person dependency, where system knowledge lives in one or two people's heads rather than in documentation.
Scoring a system across these four dimensions - even informally, on a simple high/medium/low scale - is usually enough to separate systems that merely feel old from systems that are genuinely dragging down the business. The next question is where that scoring data actually comes from.
What a software systems audit involves
A software systems audit is the mechanism that turns the four dimensions above from guesswork into evidence. Rather than relying on whoever shouts loudest in a planning meeting, an audit systematically walks through the areas that actually determine a system's health and produces documented findings that any stakeholder can review.
At a high level, a thorough IT systems audit checklist typically spans several recognizable areas.
- Architecture and system design review covers how components are structured, how tightly coupled they are, and whether the system can scale without a fundamental redesign.
- Codebase quality assessment looks at coding standards, technical debt hotspots, and automated test coverage to gauge how safely the system can be changed.
- Infrastructure and cloud configuration review examines resource utilization, backup and disaster recovery posture, and whether spend is proportional to actual usage.
- Security and compliance review checks access controls, data protection practices, and dependency vulnerabilities against relevant standards.
- Finally, documentation and delivery practices - CI/CD maturity, onboarding materials, and process consistency - often get less attention than code itself, despite being one of the strongest predictors of how expensive a system is to maintain.
Not every audit needs to cover every one of these areas. Organizations facing a specific pain point, such as runaway cloud costs or a security incident, may scope an audit narrowly around one or two modules rather than the full picture. What matters most is that whichever areas are reviewed, they're reviewed with the same rigor and documented the same way, so the resulting scores can be compared fairly across a whole systems portfolio. That consistency is also what makes the next practical question - how long this actually takes and what it requires from your team - answerable in advance.
Technical ecosystem audit: How long it takes, what you need to provide, and what you get back
One of the most common hesitations around commissioning a software systems audit is uncertainty about the disruption it will cause. In practice, a well-scoped audit is designed to run alongside normal operations rather than interrupt them, but it does require some planning on both timeline and access.
Duration depends heavily on scope. A narrow audit - say, a security and cost review of a single platform - can often be completed in two to three weeks. A comprehensive review spanning architecture, code quality, infrastructure, and delivery practices across a larger system typically takes four to six weeks, factoring in time for stakeholder interviews and documentation review rather than automated scanning alone. Multi-system portfolio audits naturally extend beyond that, usually broken into phases so early findings can inform prioritization before the full review concludes.
On the access side, most audits require read-only access to source repositories, cloud environments, and monitoring or logging tools, along with existing architecture diagrams and documentation where they exist. Auditors typically don't need - and shouldn't be given - the ability to make changes to production systems; the review itself should introduce zero operational risk.
Just as important as system access is time from key people: a handful of structured interviews with engineers, architects, and operations leads usually fills in the context that documentation alone can't capture, particularly around decisions that were never written down.
The output of a well-run audit should be more than a list of complaints. Expect a consolidated findings report scored against clear criteria, a prioritized roadmap that ranks recommendations by effort and impact rather than presenting an undifferentiated list, and enough supporting evidence - architecture diagrams, cost breakdowns, risk registers - that the findings hold up under scrutiny from both technical and non-technical stakeholders. With that evidence in hand, the fix-replace-retire framework introduced earlier stops being theoretical and becomes something you can actually apply.
Applying the framework to a software system audit: when to fix, replace, or retire
With scored evidence in hand, the framework's real value shows up in how it separates three outcomes that often get conflated in planning conversations: fixing what's fundamentally sound, replacing what isn't, and retiring what no longer earns its keep.
To fix
Fix is usually the right call when a system scores high on business criticality but only moderate on technical health, and its cost and risk exposure remain contained. These are systems worth investing in incrementally - refactoring the worst technical debt hotspots, improving test coverage, and tightening documentation - because the underlying architecture is still sound enough to support the business for years to come. Fixing is almost always cheaper and faster than replacing, provided the technical debt hasn't crossed into structural territory.
To replace
Replace becomes the stronger option when criticality remains high but technical health is poor, cost of ownership is climbing, or the architecture has hit a scalability ceiling that incremental fixes can't solve. This is the path for systems that matter enormously to the business but were built on assumptions - about scale, about integrations, about the regulatory environment - that no longer hold. Modernization here doesn't have to mean a disruptive full rewrite; a staged migration that preserves working components while replacing the parts causing the most pain is usually the more pragmatic route.
To retire
Retire applies to systems that score low on business criticality, regardless of their technical condition. A perfectly well-built system supporting a discontinued product line or a workflow that's since been consolidated elsewhere is still a retirement candidate - decommissioning it eliminates its maintenance cost and its security surface area in one move. Retirement decisions are often delayed simply because no one has explicitly confirmed the system is safe to turn off, which is itself a gap a proper audit is well suited to close.
Applying these three categories consistently across a system portfolio is what actually produces a prioritized modernization backlog rather than a pile of individually justified projects. It's also where most organizations run into the same handful of avoidable mistakes.
Common pitfalls in application rationalization
Even with a solid framework in place, a few recurring patterns tend to undermine fix-replace-retire decisions in practice, and it's worth naming them explicitly before applying the framework to a real system.
The most familiar is the sunk cost fallacy - treating the money and time already invested in a system as a reason to keep fixing it, rather than evaluating it purely on its current and future value. A system that has consumed five years of engineering effort isn't automatically worth a sixth, if the underlying evidence says otherwise.
A second common trap is the "boil the ocean" rewrite, where a legacy system risk assessment correctly identifies serious problems but the response is an all-or-nothing replacement of the entire platform at once. This concentrates risk instead of managing it, and it's precisely the scenario a staged, evidence-based roadmap is meant to avoid.
Ignoring key-person dependency is a third recurring blind spot. A system can score reasonably well on every technical metric and still represent enormous organizational risk if only one person understands how it actually works - a risk that rarely shows up until that person leaves.
Finally, many organizations treat cloud cost as a separate conversation from architecture, addressing spend through resource rightsizing alone while ignoring the structural inefficiencies driving that spend in the first place. Cost, in a proper audit, is a symptom worth tracing back to its architectural root cause rather than a line item to be trimmed in isolation. Avoiding these pitfalls is easier in the abstract than in practice, which is why it helps to see the framework applied to an actual scenario.
A worked example of a software technical audit service: scoring one ecosystem end-to-end
Consider a mid-market logistics company running a route-optimization platform built roughly eight years ago. The system is central to daily operations - dispatchers rely on it constantly, and it directly affects delivery costs and customer satisfaction. On business criticality, it scores high without much debate.
On technical health, the picture is more mixed. The core logic is sound and well-tested, but a handful of custom integrations with third-party mapping providers were built as one-off scripts with no automated tests and minimal documentation. Technical health lands in the medium range - not broken, but fragile in specific, identifiable places rather than throughout.
Total cost of ownership tells a sharper story. Cloud spend has crept up nearly 40% over two years without a corresponding increase in usage, largely due to over-provisioned compute instances that were never resized after an early scaling scare. Combined with the engineering hours spent firefighting integration failures, the system's true cost is meaningfully higher than its infrastructure invoice alone suggests.
Risk exposure adds a final, decisive factor: the engineer who built the mapping integrations left the company eighteen months ago, and no one currently on the team fully understands how they handle edge cases like address ambiguity or service-area boundaries.
Taken together, this system doesn't fit neatly into "fix" or "replace." The core platform - high criticality, fundamentally sound architecture - is a strong candidate to fix and retain. But the fragile, undocumented integration layer, carrying the bulk of both the cost overrun and the key-person risk, is a stronger candidate for targeted replacement: rebuilding those specific integrations with proper testing and documentation, rather than touching the platform as a whole. This is exactly the kind of nuanced, component-level outcome that a single up-or-down modernization decision would have missed entirely - and exactly what a structured audit is designed to surface.
Turning findings into a modernization roadmap
Scoring individual systems is only half the exercise; the real payoff comes from converting those scores into a sequenced plan the rest of the organization can act on. A modernization roadmap built on audit evidence groups findings into quick wins that can be addressed within weeks, medium-term initiatives that require dedicated engineering capacity, and longer strategic bets that may span multiple quarters - ranked by a combination of business impact and implementation effort rather than by which team complains loudest.
For organizations without the internal bandwidth or independence to run this kind of review objectively, bringing in outside expertise for a structured software systems audit can shortcut months of internal debate and produce a roadmap that's easier to defend to a board or leadership team, precisely because it isn't self-scored by the same people who built the systems under review. CIGen runs modular technical software audits along these same lines - evaluating architecture, code, infrastructure, security, and cost against the Azure Well-Architected Framework - for organizations that want an evidence-based starting point for exactly these decisions.
Whether the audit is run internally or by an outside partner, the underlying discipline is the same: separate the systems that deserve continued investment from the ones quietly draining resources, and make that separation on evidence rather than instinct.